

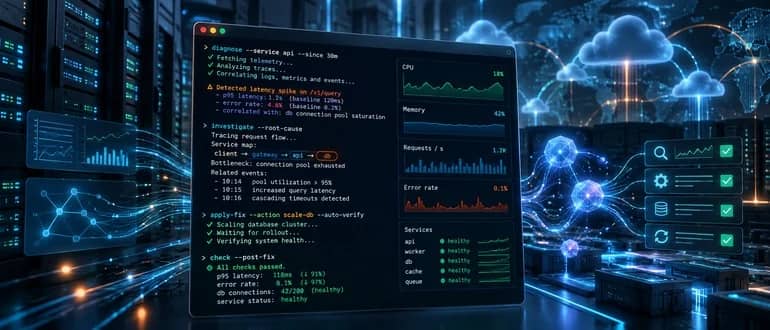
How to Move AI SRE Agents From Demo to Production
An AI agent that works on an engineer’s laptop can feel like a breakthrough. It can read logs, query observability tools, inspect cloud resources and connect a failed deployment to a bad configuration change in minutes. For a single investigation, under close human supervision, that is real progress. It is also the easy part. The […]
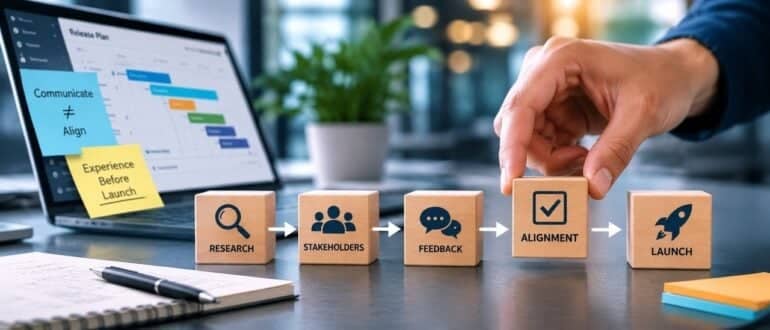
Informing Stakeholders Isn’t the Same as Aligning Them
The first sign of trouble was a screenshot. We’d just switched on the A/B test via our feature management platform. Within the hour, a senior stakeholder landed in the variant feature flag, opened the app on their own phone, and sent us an image of it. The message, more or less: “Why is there a […]
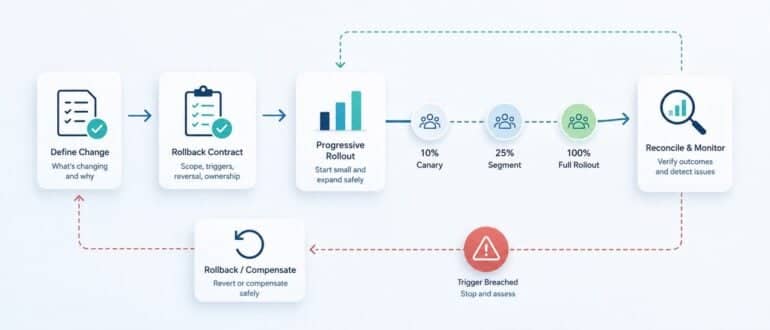
Treat Business Workflow Changes Like Deployments
Business automation often reaches production without the release discipline applied to application code. A routing rule changes, an approval threshold moves, or an integration starts writing to a new system. The edit may happen in a visual builder instead of a repository, but its blast radius is still real: orders can duplicate, customers can receive […]
Cyber Threats to DevOps Platforms Rising Fast, GitProtect Report Finds
The number of incidents targeting DevOps platforms grew 21% in 2025, but the amount of downtime jumped almost 95%, the security firm said.
Harness Adds AI Agent to Help Investigate Incidents
Harness today added an artificial intelligence (AI) agent to its portfolio that has been specifically trained to help DevOps teams investigate events that occurred prior to an incident. Tina Huang, vice president of product and engineering for AI SRE at Harness, said the Harness Human-Aware Change Agent leverages large language models (LLMs) to analyze comments […]
Typosquat Supply Chain Attack Targets Go Developers
A backdoor that impersonates a widely used database module in the popular Go programming language can give hackers control of infected systems, according to a senior threat intelligence analyst with developer-focused platform provider Socket. The malicious package, which the threat actor first published in November 2021 and remains in the Go Module Proxy, typosquats the […]
Best of 2023: ‘Scrum == Cancer’ ¦ Plus: Linux 6.5 Ships
In this week’s #TheLongView: Scrum sucks, sources say; and here comes the Linux 6.5 kernel.
Microsoft kills Python 3.7 ¦ … and VBScript ¦ Exascaling ARM on Jupiter
In this week’s #TheLongView: VS Code drops support for Python 3.7, Windows drops VBScript, and Europe plans the fastest ARM supercomputer.
Oracle Bill is 5x Client’s Budget ¦ Toyota Out of Space
In this week’s The Long View: Birmingham looks like the Detroit of the UK—is it Oracle’s fault? Plus: Was Toyota’s factory failure caused by running out of disk space?
80% of Bosses ‘Regret’ Stopping WFH ¦ PSA: Disable STS!
In this week’s #TheLongView: Rethinking return-to-office mandates and a ridiculous, ancient Windows bug.
Microsoft’s 9th Outage in 2023 ¦ RISE of RISC-V ¦ Meta Ends WFH
In this week’s #TheLongView: Redmond SaaS keeps failing, RISC-V is RISEing, and Meta is enforcing hybrid work.
Cloudflare Outage Outrage | Yet More FAA 5G Stupidity
In this week’s The Long View: Cloudflare suffers another huge outage while the FAA and FCC still disagree over 5G/NR near airports.
The Evolution of Incident Management
Have you ever thought about the history of incident management? If you’re an SRE, you might be so caught up in the day-to-day work of managing reliability and responding to incidents that you never take time to step back and reflect on the evolution of your role and your responsibilities. And that’s a shame because […]
Choosing an Incident Management Platform
When you’re feeling the stress and pain of manually managing incidents and incident response, making the decision to find an incident management tool is a no-brainer. But how do you choose the one that will work best for you, your team and your business? You might be asking yourself, “Where do I start? What do […]
Best Practices for Cloud Incident Response
Cloud computing is now mainstream, with almost all organizations running at least some resources in the public cloud—whether software-as-a-service (SaaS), platform-as-a-service (PaaS) or infrastructure-as-a-service (IaaS). Security teams have been scrambling to adapt to cloud environments, and with the growing adoption of DevSecOps, they are working together with DevOps teams to secure cloud systems from the […]
What Chaos Engineering Is (and Isn’t)
The birth of chaos engineering happened somewhat accidentally in 2008 when Netflix moved from the data center to the cloud. The move didn’t go as planned. The thinking at the time was that the data center locked Netflix into an architecture of single points of failure, like large databases and vertically scaled components. Moving to […]
SREs Say AIOps Doesn’t Live Up to the Hype
What can you expect when investing in artificial intelligence for IT operations (AIOps)? Real-time visibility across huge volumes of information. Lightning-fast event correlation and anomaly detection. Automated remediation and self-healing, without Ops personnel having to lift a finger. It all sounds amazing—at least, if you believe the marketing hype. But do those kinds of AIOps […]
Code Ownership Is Key to Accelerate Debugging
App stability is a fundamental part of every app experience. Broadly speaking, app stability is a measurement of the number of total app sessions that are crash-free or the percentage of daily active users who do not experience an error. End users have little patience for apps that crash or fail. Every application, whether it’s […]
PagerDuty Allies with JFrog to Modernize IT Incident Management
PagerDuty has integrated its IT incident management platform with the continuous integration/continuous delivery (CI/CD) platform from JFrog as part of an effort to streamline troubleshooting of application environments. Steve Gross, senior director of strategic business development at PagerDuty, said the overall goal is to make it easier for IT operations teams and developers to collaboratively […]
How IT Can Use AI To Prepare For Uncertainty
The past year has been unpredictable for businesses – from migrating to remote work to planning for a return to offices to keeping pace with shifting government guidelines. With so much in flux, it was and is a good reminder that organizations must be prepared for the unexpected and have contingency plans in place. From […]
Three Ways Machine Learning Can Change Incident Management
Incident management for important applications has many connotations, many of them negative. Most are well-deserved. Stress, panic, hurry, urgent, drop-everything, all-hands-on-deck, emergency, to name a few. Typically, there is a critical problem, ranging from complete failure to loss of certain functionality or performance. The problem or outage potentially means loss of revenue, loss of customers, […]
Blips and Downtime: Incident Management 101
Nothing gets the blood pumping like seeing an IT incident alert flash across the screen. Is the network traffic anomaly a potential intrusion? Are we about to have an outage? Is it just a random blip on the radar? The implications of these different potential incidents vary wildly, and each requires a different set of […]