

80% of Bosses ‘Regret’ Stopping WFH ¦ PSA: Disable STS!
In this week’s #TheLongView: Rethinking return-to-office mandates and a ridiculous, ancient Windows bug.

2024—Year of the Linux Desktop? ChromeOS Reflects its Inner Penguin ¦ GNOME Rethink
In this week’s #TheLongView: Can the Linux desktop installed base break the mythical 10% barrier? Google has been refactoring ChromeOS, and GNOME is working on new window manager ideas.

AI ‘is Getting Worse’ ¦ AI ‘Will Lose India Jobs’ (Probably Isn’t ¦ Probably Won’t)
In this week’s #TheLongView, a conundrum: On the one hand, researchers say ChatGPT is losing the plot; and on the other, outsourced coding jobs in India will be replaced by AI.
Forking RHEL! Oracle and SUSE Join the Fight ¦ Silverman Sues AI Firms
In this week’s #TheLongView: SUSE announces a Red Hat Enterprise Linux fork after Oracle said a similar thing, and Sarah Silverman says OpenAI and Meta have stolen her words.

Threads: Twitter Killer or Ad-Infested Hellscape?
In this week’s #TheLongView: Meta launches its much-leaked Threads microblogging app. A spinoff from Instagram, it’s already reached 30 million signups at the time of writing. How is Meta’s DevOps team making it scale?
Microsoft’s 9th Outage in 2023 ¦ RISE of RISC-V ¦ Meta Ends WFH
In this week’s #TheLongView: Redmond SaaS keeps failing, RISC-V is RISEing, and Meta is enforcing hybrid work.
US DoJ Makes PyPI Give Up User Data ¦ Tape Storage: Not Dead
In this week’s #TheLongView: PyPI complies with a “string of subpoenas,” and LTO continues to grow, despite predictions of its demise.
Predicting, Preventing and Resolving Incidents With AIOps
IT operations teams, site reliability engineers (SREs) and service providers are on a mission to scale across geographies, expand their digital services and create new experiences for customers. Amid this drive, their backend IT systems are getting more complex. This hinders visibility into applications and makes monitoring and troubleshooting cumbersome. With heightened competition in the […]
Linux Tweak Brings Big Speedup ¦ DCs in SPAAACE (Redux) ¦ Atlassian Fires 500
In this week’s #TheLongView: Intel optimizes Linux multithreaded networking, data centers in space (again), and more DevOps layoffs.
Voice.ai ‘Stole’ Code ¦ AWS Gets Filthier
In this week’s #TheLongView: Alleged theft of GPL code, and Amazon will run its data centers on gas.
Why SREs Are Critical to DevOps
Although a relatively new concept, site reliability engineers (SREs) have become crucial for DevOps teams, helping to solve an array of operational problems such as network availability and user experience. However, in previous years, some people have questioned the longevity of such a role. This article will discuss several reasons why site reliability engineering roles […]
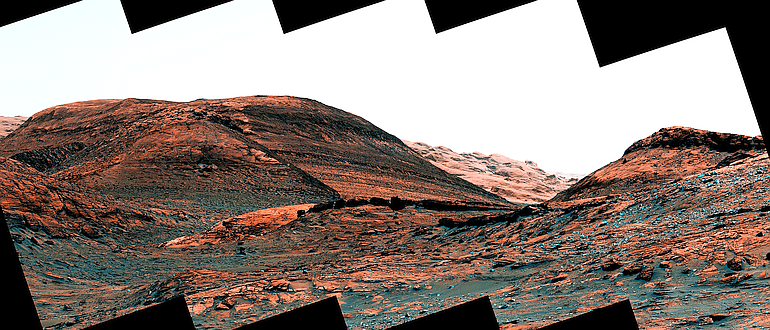
Agile Sucks (Redux) | Plus: DevOps on Mars
In this week’s The Long View: Agile is bad, but “Wagile” is worse. Plus: This prod is even worse than yours.
The Rogers Outage of 2022: Takeaways for SREs
When, eight years from now, folks are creating lists of the top IT incidents of the 2020s, there’s a good chance that they’ll include the Rogers outage of 2022. The failure, which made internet and cellular network service unavailable for more than 12 million users across Canada, was one of the most significant outages in […]
5 Ways to Prevent an Outage
In today’s always-on, ever-connected world, we all expect 100% availability. What gets in the way of this? The devil is in the details. Over time, everything breaks: Disks, nodes, containers, networks, DNS servers and configuration issues can all lead to major outages. Amazon’s 13 minutes of downtime in August 2021 translated to almost $5 million […]
Why More Incidents Are Better
Ask most SREs how many incidents they’d have to respond to in a perfect world, and their answer would probably be ‘zero.’ After all, making software and infrastructure so reliable that incidents never occur is the dream that SREs are theoretically chasing. Reducing the number of actual incidents as much as possible is a noble […]
5 Mean-Time Reliability Metrics To Follow
Most folks working in DevOps or SRE roles are familiar with metrics like mean-time-to-recovery (MTTR). Keeping track of the average time a team takes to respond to incidents is crucial to identifying bottlenecks in the support process. It’s also something executives like to show higher-ups when sharing a snapshot of overall platform performance. However, focusing […]
Site Reliability Engineering (SRE) Comes of Age in 2022
The site reliability engineer (SRE) role is still gathering steam across organizations. In January 2022, LinkedIn listed SRE as the 21st job with the highest global demand throughout the past five years. That’s pretty high for such a specific tech role. And, looking to the future, it appears the SRE practice will only continue to […]
CNCF Takes LitmusChaos Platform to the Incubation Level
The technical oversight committee (TOC) for the Cloud Native Computing Foundation (CNCF) announced today it is elevating the open source LitmusChaos application testing platform to the incubation level. LitmusChaos is a chaos engineering platform donated to the CNCF by ChaosNative in 2020. Since then, it has seen adoption within production environments by more than 25 […]
Kentik Open Sources Five Projects to Advance Network Observability
Kentik today unfurled a developer hub, dubbed Kentik Labs, through which it is making five open source projects available as part of an effort to advance observability across network operations (NetOps). The five projects are: kTranslate: A system for pulling and pushing network data that is the basis of the Kentik Firehose integration the company […]
Where Do SREs Go From Here?
Charlene O’Hanlon talks with Leo Vasiliou, director of product marketing at Catchpoint, about the results of a study the company fielded with VMWare Tanzu and DevOps Institute of nearly 300 site reliability engineers (SREs). This year’s report underscores the challenges of multi-cloud, calls out the underutilization of AIOps and shows a systemic shift in core […]
How to Build an Options-Based Observability Strategy
The global pandemic forced companies to accelerate their digital transformations, pushing them toward new technologies and architectures as they struggled to adapt to a changing world. Companies wanted fast development and deployment and were happy to trade off efficiency, reliability and sometimes, security, to pursue their goals. Now that the pandemic is receding in many […]
12 Ways to Bake Security Into a DevOps Transformation
Security has become an integral part of any DevOps transformation. According to the Upskilling 2021: Enterprise DevOps Skills Report, DevSecOps achieved a must-have percentage vote of 56% in the automation tool category. Security not only protects the business and its customers, but it enables companies to enforce internal and external policies. While considering how to […]
Survey Reveals Slight Decline in Level of SRE Toil
The amount of routine toil that site reliability engineers (SREs) perform declined slightly in the last year even though IT environments in general are becoming more complex to manage. An annual survey of 300 SREs conducted by Catchpoint, a provider of an IT monitoring platform, in collaboration with VMware and the DevOps Institute suggests that […]