Tag: SRE
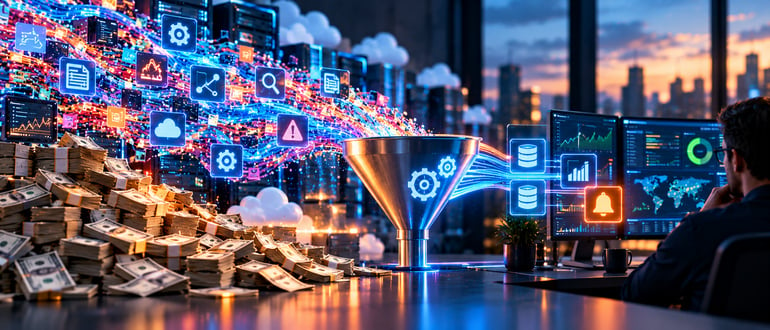
The Observability Tax: When Monitoring Costs Exceed Downtime Costs
 Muhammad Yawar Malik | | cloud costs, data retention, devops, Distributed Tracing, FinOps, incident response, infrastructure monitoring, logs, metrics, observability, observability costs, observability strategy, OpenTelemetry, platform engineering, SRE, telemetry, telemetry costs, traces
Observability costs can spiral when teams collect more telemetry than they actually use. A more mature approach prioritizes the data that directly improves incident detection, diagnosis and recovery ...
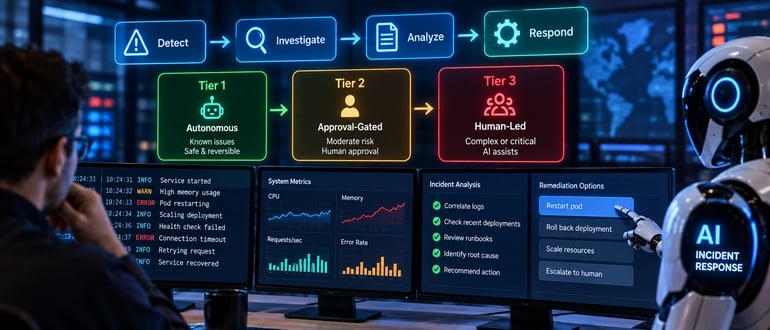
The Three Tiers of Agentic Incident Response: When to Trust AI Autonomy
 Neel Shah | | agentic AI, AI agents, AI Governance, AI operations, AIOps, automation guardrails, autonomous remediation, devops, human-in-the-loop, incident management, incident response, mttr, observability, production reliability, Runbooks, site reliability engineering, SRE
A three-tier model for agentic incident response balances AI automation with human oversight, matching autonomy to risk, reversibility, blast radius and diagnostic confidence ...
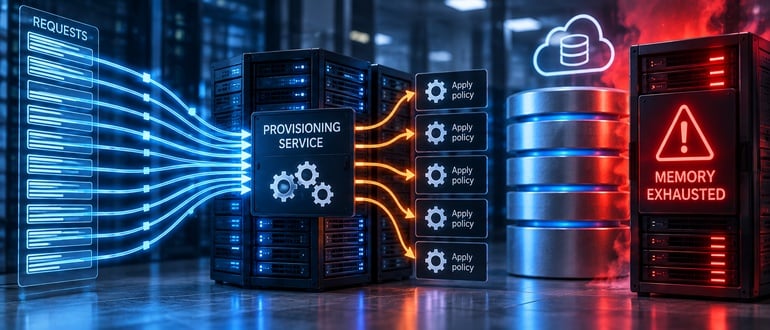
The Most Dangerous Reliability Failures Aren’t Component Failures
 Semyon Slepov | | architecture, cloud infrastructure, concurrency, devops, Incident Analysis, memory exhaustion, Production Failures, provisioning systems, reliability engineering, resource limits, SRE, STPA, system design, system reliability, systems safety, workload management
A production provisioning failure shows why reliability problems can emerge from interactions between healthy components, and how system-level constraints and feedback can prevent them ...
Observability’s Gaslighting Problem: “Send Less Data” Isn’t a Strategy
 Noam Levy | | agentic development, AI agents, AI-assisted development, cardinality, data retention, developer observability, devops, incident response, logs, metrics, observability, observability costs, observability strategy, Runtime Visibility, software reliability, SRE, telemetry, Telemetry Optimization, telemetry sampling, traces
A familiar pattern is emerging in observability conversations. As telemetry volumes grow and costs rise, the default recommendation is often to collect less data: Sample more, retain less, index selectively, filter earlier, ...
Automated Diagnosis Isn’t Automated Understanding: What Postmortems Teach Us About Building Trustworthy Incident AI
 Jyostna Seelam | | AI incident response, AI observability, AI reliability, AIOps, alert correlation, automated incident response, causal reasoning, dependency graphs, devops, Engineering leadership, human-in-the-loop, incident diagnosis, incident management, LLM operations, non-deterministic systems, on-call engineering, postmortems, RAG systems, root cause analysis, SRE
AI incident tools can reduce alert noise, but real root-cause diagnosis requires causal reasoning, live dependency context, uncertainty handling and strong postmortem data ...
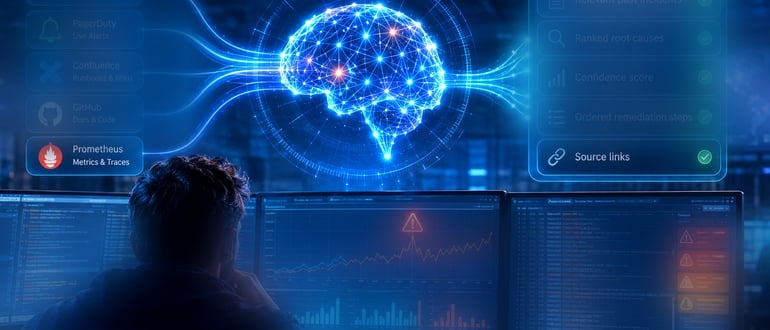
Beyond Log Search: What We Learned Building a RAG-Based Incident Diagnosis System
 Abhimanyu Garg | | AI for SRE, AI hallucinations, AI incident diagnosis, AIOps, devops, devops automation, FAISS, incident management, incident remediation, incident response, knowledge management, knowledge retrieval, LLM grounding, LLM incident response, observability, postmortems, production AI, RAG AIOps, re-ranking, retrieval-augmented generation, root cause analysis, Runbooks, semantic search, SRE
A RAG-based AIOps framework can cut incident diagnosis time by grounding LLM reasoning in real runbooks, tickets and postmortems, improving root-cause accuracy while giving SREs source-backed answers they can trust ...

Mezmo Open Sources AI SRE Operations

Site reliability engineering has been quietly buckling under its own success. The scope of what SRE teams are expected to own — observability, incident response, telemetry pipelines, capacity, cost, resilience — keeps ...
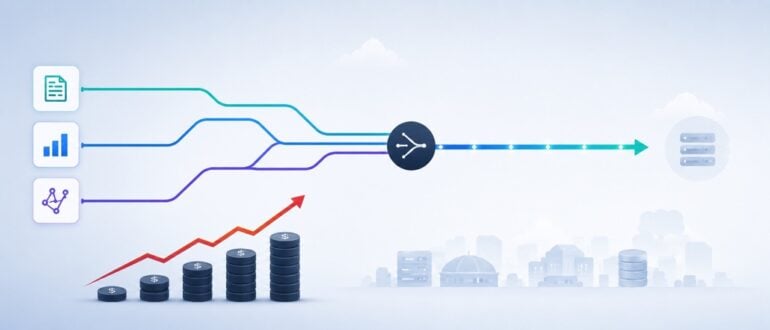
Why Your Observability Stack Is Costing You More Than Your Cloud Bill

There's a pattern playing out across engineering teams right now that nobody talks about openly: the tool meant to reduce operational complexity has quietly become one of the biggest line items on ...
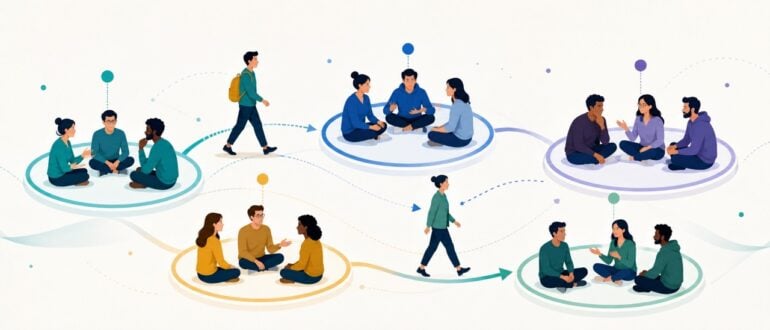
When the Structure Becomes the Culture

Why micro teams and rotation reshape culture, not just throughput, in modern SRE. Most SRE leaders design teams around the systems they own. We designed ours around movement. We introduced micro teams ...

The Death of the Four Golden Signals: Designing Telemetry for Non-Deterministic Infrastructure
Jyostna Seelam | | AI architecture, AI compliance, AI Governance, AI guardrails, AI infrastructure, AI monitoring, AI observability, AI operations, AI operations strategy., AI performance metrics, AI platform monitoring, AI reliability, AI resilience, AI safety, AI SLIs, AI SLOs, AI system reliability, AI telemetry, AI trust, Enterprise AI, generative AI monitoring, guardrail intervention rate, hallucination detection, LLM monitoring, LLM observability, modern SRE, non-deterministic systems, Observability Engineering, OpenTelemetry, platform engineering, production AI, RAG observability, RAG systems, semantic drift, site reliability engineering, SRE, time to first token, token throughput, TTFT, vector database monitoringIn complex software systems, our traditional definition of operational health has always been comfortably binary. For over a decade, site reliability engineering (SRE) teams have relied on the industry-standard ‘Four Golden Signals’ ...

Agentic SRE: The Next Frontier of Reliability
Agentic SRE is the evolution of site reliability engineering where AI agents help observe systems, reason over telemetry and take bounded operational actions under human-defined guardrails ...

On-Call: The Silent Force Shaping Engineering Culture

There is a silent force shaping engineering culture inside every technology organization. It affects productivity, team morale, psychological safety, and long-term retention. And yet, it is rarely discussed in executive meetings or ...

